第 5 章:工具使用(函数调用)
工具使用模式概览
前文讨论的模式,主要关注如何编排语言模型之间的交互,以及如何管理智能体内部工作流中的信息流(链式、路由、并行与反思)。但若要真正与外部系统乃至现实世界交互,智能体还必须具备使用工具能力。
工具使用模式通常通过「函数调用」(Function Calling)实现,使智能体能够调用外部 API、数据库、服务,甚至执行代码。位于核心的大语言模型,会根据用户请求或任务当前状态,决定是否调用某个外部函数,以及如何调用。
一般包括以下步骤:
- 工具定义: 向 LLM 描述外部函数或能力,包括用途、名称、参数及其类型说明。
- LLM 决策: LLM 接收用户请求和可用工具定义,判断是否需要调用一个或多个工具。
- 函数调用生成: 若需要调用工具,LLM 会生成结构化输出(通常为 JSON),指明工具名称和参数。
- 工具执行: 框架或编排层拦截该输出,找到对应工具,并用给定参数执行真实函数。
- 结果返回: 工具执行结果返回给智能体。
- LLM 再处理(可选但常见): LLM 将工具结果纳入上下文,用它生成最终回复,或决定下一步(例如继续调用工具、进行反思,或直接作答)。
这一模式的重要性在于,它突破了训练数据的边界:让模型能够获取最新信息、完成自身不擅长的计算、访问用户专属数据,甚至触发真实世界中的动作。函数调用(Function Calling) 正是连接 LLM 推理能力与外部功能的技术桥梁。
「函数调用」准确描述了对预定义代码函数的调用,但「工具调用」的视角更宽:工具不仅可以是传统函数,也可以是复杂 API、数据库查询,甚至是发给另一位专精智能体的指令。这样一来,我们就能构想更复杂的系统,例如主智能体将数据分析任务委派给「分析师智能体」,或通过 API 查询外部知识库。用「工具调用」来理解,更能体现智能体作为编排者连接多种数字资源与其他智能体的潜力。
LangChain、LangGraph、Google ADK 等框架都为工具定义和集成提供了成熟支持,并常结合 Gemini、OpenAI 等模型的原生函数调用能力。在这些框架中,先定义工具,再配置智能体(通常是 LLM Agent),让它能够识别并调用这些工具。
工具使用是构建强大、可交互且具备外部感知能力的智能体的基石模式。
实际应用与用例
只要智能体不只是生成文本,而是需要执行动作或获取动态信息,工具使用模式几乎都适用:
1. 从外部来源检索信息
获取训练数据中不存在或已过时的实时信息与数据。
- 用例: 天气智能体。
- 工具: 接收地点并返回当前天气状况的天气 API。
- 流程: 用户问「伦敦天气如何?」→ LLM 判断需要调用天气工具 → 以
London为参数调用 → 工具返回数据 → LLM 整理成易读回复。
2. 与数据库和 API 交互
对结构化数据执行查询、更新或其他操作。
- 用例: 电商智能体。
- 工具: 用于查询库存、订单状态或处理支付的 API。
- 流程: 用户问「X 有没有货?」→ LLM 调用库存 API → 返回数量 → LLM 告知库存情况。
3. 执行计算与数据分析
借助外部计算器、数据分析库或统计工具完成计算与分析。
- 用例: 金融智能体。
- 工具: 计算函数、股市行情 API、电子表格工具等。
- 流程: 用户询问 AAPL 现价,以及若以 150 美元买入 100 股的潜在收益 → LLM 先调用股价 API → 再调用计算工具 → 整理成清晰回答。
4. 发送通信内容
发送邮件或消息,或调用外部通信类服务 API。
- 用例: 个人助理智能体。
- 工具: 邮件发送 API。
- 流程: 用户说「给 John 发邮件说明天开会的事」→ LLM 从请求中抽取收件人、主题、正文并调用邮件工具。
5. 执行代码
在安全环境中运行代码片段以完成特定任务。
- 用例: 编程助手智能体。
- 工具: 代码解释器。
- 流程: 用户提供 Python 片段并问「这段代码做什么?」→ LLM 通过解释器运行代码并分析输出。
6. 控制其他系统或设备
与智能家居设备、物联网平台或其他联网系统交互。
- 用例: 智能家居智能体。
- 工具: 控制智能灯具的 API。
- 流程: 用户说「关掉客厅灯」→ LLM 携带命令与目标设备信息调用智能家居工具。
借助工具,语言模型才能从单纯的文本生成器,转变为能够在数字或物理环境中感知、推理并行动的智能体(见图 1)。
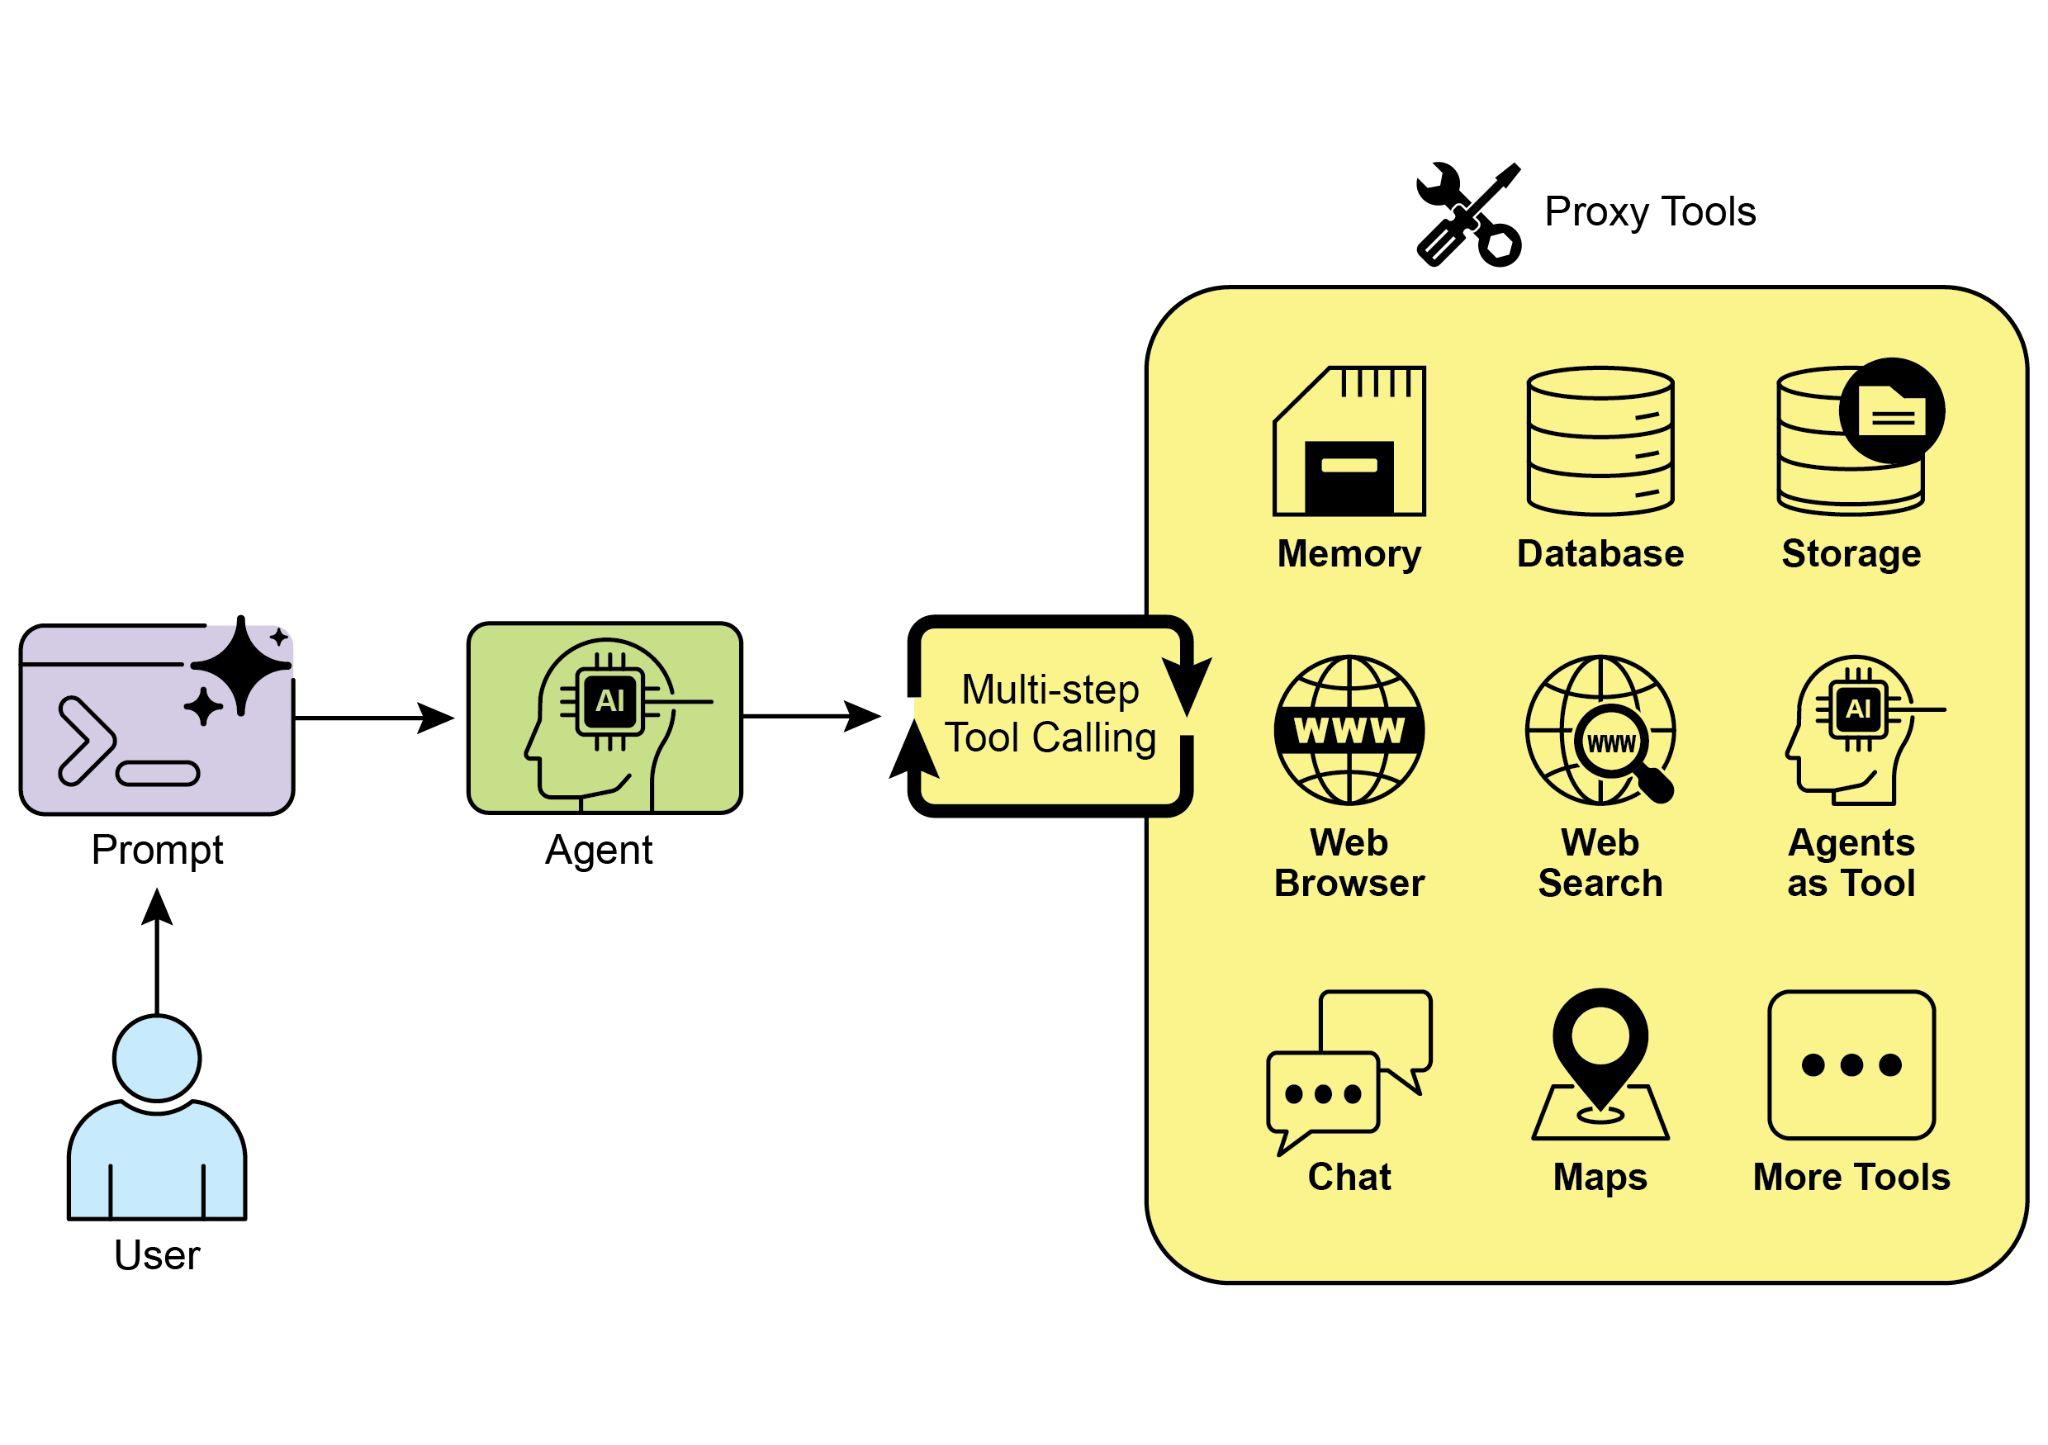
图 1:智能体使用工具的若干示例。
动手代码示例(LangChain)
在 LangChain 中实现工具使用通常分两步:先定义一个或多个工具(通常把现有 Python 函数或其他可运行组件封装为工具),再把它们绑定到语言模型,使模型在判断需要外部函数调用时,能够发出结构化的调用请求。
下面的示例先用一个简单函数模拟信息检索工具,再搭建并配置智能体,让它能根据用户输入调用该工具。运行前需安装 LangChain 核心库和相应的模型提供方包,并在本地环境中配置 API 密钥完成鉴权。
import os
import getpass
import asyncio
import nest_asyncio
from typing import List
from dotenv import load_dotenv
import logging

from langchain_google_genai import ChatGoogleGenerativeAI
from langchain_core.prompts import ChatPromptTemplate
from langchain_core.tools import tool as langchain_tool
from langchain.agents import create_tool_calling_agent, AgentExecutor

# UNCOMMENT
# Prompt the user securely and set API keys as environment variables
os.environ["GOOGLE_API_KEY"] = getpass.getpass("Enter your Google API key: ")
os.environ["OPENAI_API_KEY"] = getpass.getpass("Enter your OpenAI API key: ")

try:
    # A model with function/tool calling capabilities is required.
    llm = ChatGoogleGenerativeAI(model="gemini-2.0-flash", temperature=0)
    print(f"✅ Language model initialized: {llm.model}")
except Exception as e:
    print(f"🛑 Error initializing language model: {e}")
    llm = None

# --- Define a Tool ---
@langchain_tool
def search_information(query: str) -> str:
    """
    Provides factual information on a given topic. Use this tool to find answers to phrases
    like 'capital of France' or 'weather in London?'.
    """
    print(f"\n--- 🛠️ Tool Called: search_information with query: '{query}' ---")

    # Simulate a search tool with a dictionary of predefined results.
    simulated_results = {
        "weather in london": "The weather in London is currently cloudy with a temperature of 15°C.",
        "capital of france": "The capital of France is Paris.",
        "population of earth": "The estimated population of Earth is around 8 billion people.",
        "tallest mountain": "Mount Everest is the tallest mountain above sea level.",
        "default": f"Simulated search result for '{query}': No specific information found, but the topic seems interesting.",
    }
    result = simulated_results.get(query.lower(), simulated_results["default"])
    print(f"--- TOOL RESULT: {result} ---")
    return result

tools = [search_information]

# --- Create a Tool-Calling Agent ---
if llm:
    # This prompt template requires an `agent_scratchpad` placeholder for the agent's internal steps.
    agent_prompt = ChatPromptTemplate.from_messages([
        ("system", "You are a helpful assistant."),
        ("human", "{input}"),
        ("placeholder", "{agent_scratchpad}"),
    ])

    # Create the agent, binding the LLM, tools, and prompt together.
    agent = create_tool_calling_agent(llm, tools, agent_prompt)

    # AgentExecutor is the runtime that invokes the agent and executes the chosen tools.
    # The 'tools' argument is not needed here as they are already bound to the agent.
    agent_executor = AgentExecutor(agent=agent, verbose=True, tools=tools)

async def run_agent_with_tool(query: str):
    """Invokes the agent executor with a query and prints the final response."""
    print(f"\n--- 🏃 Running Agent with Query: '{query}' ---")
    try:
        response = await agent_executor.ainvoke({"input": query})
        print("\n--- ✅ Final Agent Response ---")
        print(response["output"])
    except Exception as e:
        print(f"\n🛑 An error occurred during agent execution: {e}")

async def main():
    """Runs all agent queries concurrently."""
    tasks = [
        run_agent_with_tool("What is the capital of France?"),
        run_agent_with_tool("What's the weather like in London?"),
        run_agent_with_tool("Tell me something about dogs."),  # Should trigger the default tool response
    ]
    await asyncio.gather(*tasks)

nest_asyncio.apply()
asyncio.run(main())上述代码用 LangChain 与 Google Gemini 搭建了一个工具调用智能体。search_information 用来模拟事实检索,对「weather in london」「capital of france」「population of earth」等查询返回预设结果,其余情况走默认分支。代码先初始化具备工具调用能力的 ChatGoogleGenerativeAI,再用 ChatPromptTemplate 构造提示;create_tool_calling_agent 把模型、工具和提示组装成智能体,AgentExecutor 负责执行与调度工具。run_agent_with_tool 异步发起查询并打印结果,main 并发运行多条查询以覆盖不同路径;最后通过 asyncio.run(main()) 执行整个示例。只有在 LLM 初始化成功后,后续构建与执行才会继续。
动手代码示例(CrewAI)
本示例演示如何在 CrewAI 中实现函数调用:给智能体配一个行情查询工具,再用它查询模拟股价。
# pip install crewai langchain-openai

import os
from crewai import Agent, Task, Crew
from crewai.tools import tool
import logging

# --- Best Practice: Configure Logging ---
# A basic logging setup helps in debugging and tracking the crew's execution.
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')

# --- Set up your API Key ---
# For production, it's recommended to use a more secure method for key management
# like environment variables loaded at runtime or a secret manager.
#
# Set the environment variable for your chosen LLM provider (e.g., OPENAI_API_KEY)
# os.environ["OPENAI_API_KEY"] = "YOUR_API_KEY"
# os.environ["OPENAI_MODEL_NAME"] = "gpt-4o"

# --- 1. Refactored Tool: Returns Clean Data ---
# The tool now returns raw data (a float) or raises a standard Python error.
# This makes it more reusable and forces the agent to handle outcomes properly.
@tool("Stock Price Lookup Tool")
def get_stock_price(ticker: str) -> float:
    """
    Fetches the latest simulated stock price for a given stock ticker symbol.
    Returns the price as a float. Raises a ValueError if the ticker is not found.
    """
    logging.info(f"Tool Call: get_stock_price for ticker '{ticker}'")
    simulated_prices = {
        "AAPL": 178.15,
        "GOOGL": 1750.30,
        "MSFT": 425.50,
    }
    price = simulated_prices.get(ticker.upper())
    if price is not None:
        return price
    else:
        # Raising a specific error is better than returning a string.
        # The agent is equipped to handle exceptions and can decide on the next action.
        raise ValueError(f"Simulated price for ticker '{ticker.upper()}' not found.")

# --- 2. Define the Agent ---
# The agent definition remains the same, but it will now leverage the improved tool.
financial_analyst_agent = Agent(
    role='Senior Financial Analyst',
    goal='Analyze stock data using provided tools and report key prices.',
    backstory="You are an experienced financial analyst adept at using data sources to find stock information. You provide clear, direct answers.",
    verbose=True,
    tools=[get_stock_price],
    # Allowing delegation can be useful, but is not necessary for this simple task.
    allow_delegation=False,
)

# --- 3. Refined Task: Clearer Instructions and Error Handling ---
# The task description is more specific and guides the agent on how to react
# to both successful data retrieval and potential errors.
analyze_aapl_task = Task(
    description=(
        "What is the current simulated stock price for Apple (ticker: AAPL)? "
        "Use the 'Stock Price Lookup Tool' to find it. "
        "If the ticker is not found, you must report that you were unable to retrieve the price."
    ),
    expected_output=(
        "A single, clear sentence stating the simulated stock price for AAPL. "
        "For example: 'The simulated stock price for AAPL is $178.15.' "
        "If the price cannot be found, state that clearly."
    ),
    agent=financial_analyst_agent,
)

# --- 4. Formulate the Crew ---
# The crew orchestrates how the agent and task work together.
financial_crew = Crew(
    agents=[financial_analyst_agent],
    tasks=[analyze_aapl_task],
    verbose=True  # Set to False for less detailed logs in production
)

# --- 5. Run the Crew within a Main Execution Block ---
# Using a __name__ == "__main__": block is a standard Python best practice.
def main():
    """Main function to run the crew."""
    # Check for API key before starting to avoid runtime errors.
    if not os.environ.get("OPENAI_API_KEY"):
        print("ERROR: The OPENAI_API_KEY environment variable is not set.")
        print("Please set it before running the script.")
        return

    print("\n## Starting the Financial Crew...")
    print("---------------------------------")

    # The kickoff method starts the execution.
    result = financial_crew.kickoff()

    print("\n---------------------------------")
    print("## Crew execution finished.")
    print("\nFinal Result:\n", result)

if __name__ == "__main__":
main()该示例用 CrewAI 模拟一项金融分析任务:自定义工具 get_stock_price 用于查询预设股票代码的模拟股价,合法代码返回浮点数,未知代码则抛出 ValueError。随后创建担任高级金融分析师角色的 financial_analyst_agent,并挂载该工具;任务 analyze_aapl_task 明确要求借助工具查询 AAPL 的模拟价格,并说明成功和失败时该如何表述。接着将智能体与任务组成 Crew,并开启 verbose 以便观察日志。脚本在标准的 if __name__ == "__main__": 块中通过 kickoff() 执行任务,启动前会先检查是否已设置 OPENAI_API_KEY,结束后再把结果打印到控制台。整体上,它展示了如何在 CrewAI 中定义工具、智能体与任务,并组装成协作式工作流。
动手代码示例(Google ADK)
Google 智能体开发套件(ADK)内置了多种可与智能体能力原生集成的工具。
Google 搜索: 其中典型代表是 Google Search 工具——它直接对接 Google 搜索引擎,使智能体能够进行网页检索并获取外部信息。
from google.adk.agents import Agent as ADKAgent
from google.adk.runners import Runner
from google.adk.sessions import InMemorySessionService
from google.adk.tools import google_search
from google.genai import types
import nest_asyncio
import asyncio

# Define variables required for Session setup and Agent execution
APP_NAME = "Google Search Agent"
USER_ID = "user1234"
SESSION_ID = "1234"

# Define Agent with access to search tool
root_agent = ADKAgent(
    name="basic_search_agent",
    model="gemini-2.0-flash-exp",
    description="Agent to answer questions using Google Search.",
    instruction="I can answer your questions by searching the internet. Just ask me anything!",
    tools=[google_search],  # Google Search is a pre-built tool to perform Google searches.
)

# Agent Interaction
async def call_agent(query: str):
    """
    Helper function to call the agent with a query.
    """
    # Session and Runner
    session_service = InMemorySessionService()
    await session_service.create_session(
        app_name=APP_NAME,
        user_id=USER_ID,
        session_id=SESSION_ID,
    )

    runner = Runner(agent=root_agent, app_name=APP_NAME, session_service=session_service)

    content = types.Content(role='user', parts=[types.Part(text=query)])
    events = runner.run(user_id=USER_ID, session_id=SESSION_ID, new_message=content)

    for event in events:
        if event.is_final_response() and event.content:
            # Safely extract text from the final response
            if hasattr(event.content, "text") and event.content.text:
                final_response = event.content.text
            elif event.content.parts:
                final_response = "".join(
                    part.text for part in event.content.parts if getattr(part, "text", None)
                )
            else:
                final_response = ""
            print("Agent Response:", final_response)

nest_asyncio.apply()
asyncio.run(call_agent("what's the latest ai news?"))该示例展示如何用 Google ADK for Python 创建并运行一个基础智能体,并以 Google Search 为工具回答问题。代码导入 google.adk、google.genai 等相关库,定义应用名、用户 ID、会话 ID 等常量;接着创建名为 basic_search_agent 的 Agent,写明描述与指令,并挂载 ADK 预置的 Google Search 工具。随后初始化 InMemorySessionService(详见第 8 章)来管理会话,并通过 Runner 将智能体与会话服务连接起来。辅助函数 call_agent 会把用户查询封装为 types.Content,调用 runner.run 并遍历事件,找到最终响应后抽取文本并打印。最后以查询「what's the latest ai news?」演示智能体运行。
代码执行: ADK 还提供动态代码执行环境。内置的代码执行工具为智能体提供沙箱化 Python 解释器,使模型能够编写并运行代码,以完成数值计算、操作数据结构或执行过程式脚本。对于需要确定性逻辑与精确演算、难以仅靠概率性文本生成解决的问题,这类能力尤为关键。
import os
import getpass
import asyncio
import nest_asyncio
from typing import List
from dotenv import load_dotenv
import logging

from google.adk.agents import Agent as ADKAgent, LlmAgent
from google.adk.runners import Runner
from google.adk.sessions import InMemorySessionService
from google.adk.tools import google_search
from google.adk.code_executors import BuiltInCodeExecutor
from google.genai import types

# Define variables required for Session setup and Agent execution
APP_NAME = "calculator"
USER_ID = "user1234"
SESSION_ID = "session_code_exec_async"

# Agent Definition
code_agent = LlmAgent(
    name="calculator_agent",
    model="gemini-2.0-flash",
    code_executor=BuiltInCodeExecutor(),
    instruction="""You are a calculator agent.
    When given a mathematical expression, write and execute Python code to calculate the result.
    Return only the final numerical result as plain text, without markdown or code blocks.
    """,
    description="Executes Python code to perform calculations.",
)

# Agent Interaction (Async)
async def call_agent_async(query: str):
    # Session and Runner
    session_service = InMemorySessionService()
    await session_service.create_session(app_name=APP_NAME, user_id=USER_ID, session_id=SESSION_ID)

    runner = Runner(agent=code_agent, app_name=APP_NAME, session_service=session_service)

    content = types.Content(role='user', parts=[types.Part(text=query)])
    print(f"\n--- Running Query: {query} ---")

    try:
        # Use run_async
        async for event in runner.run_async(user_id=USER_ID, session_id=SESSION_ID, new_message=content):
            print(f"Event ID: {event.id}, Author: {event.author}")

            if event.content and event.content.parts and event.is_final_response():
                for part in event.content.parts:  # Iterate through all parts
                    if getattr(part, "executable_code", None):
                        # Access the actual code string via .code
                        print(f"  Debug: Agent generated code:\n```python\n{part.executable_code.code}\n```")
                    elif getattr(part, "code_execution_result", None):
                        # Access outcome and output correctly
                        print(
                            "  Debug: Code Execution Result: "
                            f"{part.code_execution_result.outcome} - Output:\n{part.code_execution_result.output}"
                        )
                    elif getattr(part, "text", None) and not part.text.isspace():
                        # Also print any text parts found in any event for debugging
                        print(f"  Text: '{part.text.strip()}'")

                # --- Check for final response AFTER specific parts ---
                text_parts = [part.text for part in event.content.parts if getattr(part, "text", None)]
                final_result = "".join(text_parts)
                print(f"==> Final Agent Response: {final_result}")

    except Exception as e:
        print(f"ERROR during agent run: {e}")

    print("-" * 30)

# Main async function to run the examples
async def main():
    await call_agent_async("Calculate the value of (5 + 7) * 3")
    await call_agent_async("What is 10 factorial?")

# Execute the main async function
try:
    nest_asyncio.apply()
    asyncio.run(main())
except RuntimeError as e:
    # Handle specific error when running asyncio.run in an already running loop (like Jupyter/Colab)
    if "cannot be called from a running event loop" in str(e):
        print("\nRunning in an existing event loop (like Colab/Jupyter).")
        print("Please run `await main()` in a notebook cell instead.")
        # If in an interactive environment like a notebook, you might need to run:
        # await main()
    else:
raise e # Re-raise other runtime errors该脚本基于 Google ADK 构建了一个通过编写并执行 Python 代码来解决数学问题的智能体:LlmAgent 被明确设定为计算器角色,并配备内置代码执行工具。核心逻辑在 call_agent_async 中,即向 runner 提交用户查询并处理返回的事件流;函数内部以异步方式遍历事件,打印生成的代码及其执行结果以便调试,并区分中间步骤与包含数值答案的最终事件。main 再用两个数学表达式调用该智能体,演示其计算能力。
企业搜索: 这一段代码使用 Python 的 google.adk 定义应用,并通过 VSearchAgent 在指定的 Vertex AI Search 数据存储上检索并回答问题。代码先初始化名为 q2_strategy_vsearch_agent 的智能体,包含描述、模型 gemini-2.0-flash-exp,以及通过环境变量传入的 DATASTORE_ID;再配合 Runner 与 InMemorySessionService 维护对话历史。call_vsearch_agent_async 负责构建用户消息、调用 run_async,并将回复流式输出到控制台,同时在最终响应处打印来自数据存储的溯源信息;若执行过程中发生异常,也会提示可能是数据存储 ID 错误或权限不足。run_vsearch_example 则提供了示例查询。主入口会先确认 DATASTORE_ID 已设置,再通过 asyncio.run 运行示例,并兼容 Jupyter 等已存在事件循环的环境。
import asyncio
import os

from google.genai import types
from google.adk import agents
from google.adk.runners import Runner
from google.adk.sessions import InMemorySessionService

# --- Configuration ---
# Ensure you have set your GOOGLE_API_KEY and DATASTORE_ID environment variables
# For example:
# os.environ["GOOGLE_API_KEY"] = "YOUR_API_KEY"
# os.environ["DATASTORE_ID"] = "YOUR_DATASTORE_ID"
DATASTORE_ID = os.environ.get("DATASTORE_ID")

# --- Application Constants ---
APP_NAME = "vsearch_app"
USER_ID = "user_123"  # Example User ID
SESSION_ID = "session_456"  # Example Session ID

# --- Agent Definition (Updated with the newer model from the guide) ---
vsearch_agent = agents.VSearchAgent(
    name="q2_strategy_vsearch_agent",
    description="Answers questions about Q2 strategy documents using Vertex AI Search.",
    model="gemini-2.0-flash-exp",  # Updated model based on the guide's examples
    datastore_id=DATASTORE_ID,
    model_parameters={"temperature": 0.0},
)

# --- Runner and Session Initialization ---
runner = Runner(
    agent=vsearch_agent,
    app_name=APP_NAME,
    session_service=InMemorySessionService(),
)

# --- Agent Invocation Logic ---
async def call_vsearch_agent_async(query: str):
    """Initializes a session and streams the agent's response."""
    print(f"User: {query}")
    print("Agent: ", end="", flush=True)
    try:
        # Construct the message content correctly
        content = types.Content(role='user', parts=[types.Part(text=query)])

        # Process events as they arrive from the asynchronous runner
        async for event in runner.run_async(
            user_id=USER_ID,
            session_id=SESSION_ID,
            new_message=content,
        ):
            # For token-by-token streaming of the response text
            if hasattr(event, "content_part_delta") and event.content_part_delta:
                print(event.content_part_delta.text, end="", flush=True)

            # Process the final response and its associated metadata
            if event.is_final_response():
                print()  # Newline after the streaming response
                if getattr(event, "grounding_metadata", None):
                    print(
                        f"  (Source Attributions: "
                        f"{len(event.grounding_metadata.grounding_attributions)} sources found)"
                    )
                else:
                    print("  (No grounding metadata found)")
                print("-" * 30)
    except Exception as e:
        print(f"\nAn error occurred: {e}")
        print("Please ensure your datastore ID is correct and that the service account has the necessary permissions.")
        print("-" * 30)

# --- Run Example ---
async def run_vsearch_example():
    # Replace with a question relevant to YOUR datastore content
    await call_vsearch_agent_async("Summarize the main points about the Q2 strategy document.")
    await call_vsearch_agent_async("What safety procedures are mentioned for lab X?")

# --- Execution ---
if __name__ == "__main__":
    if not DATASTORE_ID:
        print("Error: DATASTORE_ID environment variable is not set.")
    else:
        try:
            asyncio.run(run_vsearch_example())
        except RuntimeError as e:
            # This handles cases where asyncio.run is called in an environment
            # that already has a running event loop (like a Jupyter notebook).
            if "cannot be called from a running event loop" in str(e):
                print("Skipping execution in a running event loop. Please run this script directly.")
            else:
raise e总体而言,这段代码提供了一个基础骨架,用于构建借助 Vertex AI Search、基于数据存储内容回答问题的对话式应用。它演示了如何定义智能体、配置 Runner,以及如何异步交互并流式接收回复,重点是从特定数据存储中检索并整合信息以回答用户查询。
Vertex 扩展: Vertex AI 扩展是一种结构化 API 封装,使模型能够连接外部 API,进行实时数据处理并执行各类操作,同时在安全性、数据隐私与性能层面提供企业级保障。它可用于生成并运行代码、查询网站、分析私有数据存储中的信息等场景。Google 提供了 Code Interpreter、Vertex AI Search 等预置扩展,也支持开发者自定义扩展。它的主要价值在于更强的企业级管控能力,以及与 Google 产品体系的顺畅集成。它与函数调用的关键差异在于执行方式:Vertex AI 会自动执行扩展,而函数调用通常仍需由用户或客户端手动触发。
速览
是什么: LLM 虽然是强大的文本生成器,但本质上与外部世界隔绝:知识是静态的,受限于训练语料,既不能主动执行动作,也难以获取实时信息。因此,它无法独立完成依赖外部 API、数据库或服务的任务;如果缺少与这些系统连接的桥梁,它在解决真实问题时的效用就会大打折扣。
为什么: 工具使用模式(通常通过函数调用实现)为此提供了一套标准做法:先以 LLM 可理解的方式描述可用的外部函数或「工具」;面对用户请求,具备智能体能力的 LLM 再判断是否需要调用工具,并生成结构化数据(如 JSON),指明调用哪个函数以及传入哪些参数;随后由编排层执行调用、取回结果并回传给 LLM,使其能够把最新的外部信息或动作结果纳入最终回复。换言之,这一模式实质上赋予了模型「行动」能力。
经验法则: 当智能体必须跳出模型内部知识、与外部世界交互时,就应采用工具使用模式。它尤其适用于需要实时数据(如天气、股价)、访问私有或专有信息(如公司数据库)、进行精确计算、执行代码,或在其他系统中触发动作(如发邮件、控制智能设备)的任务。
图示摘要:
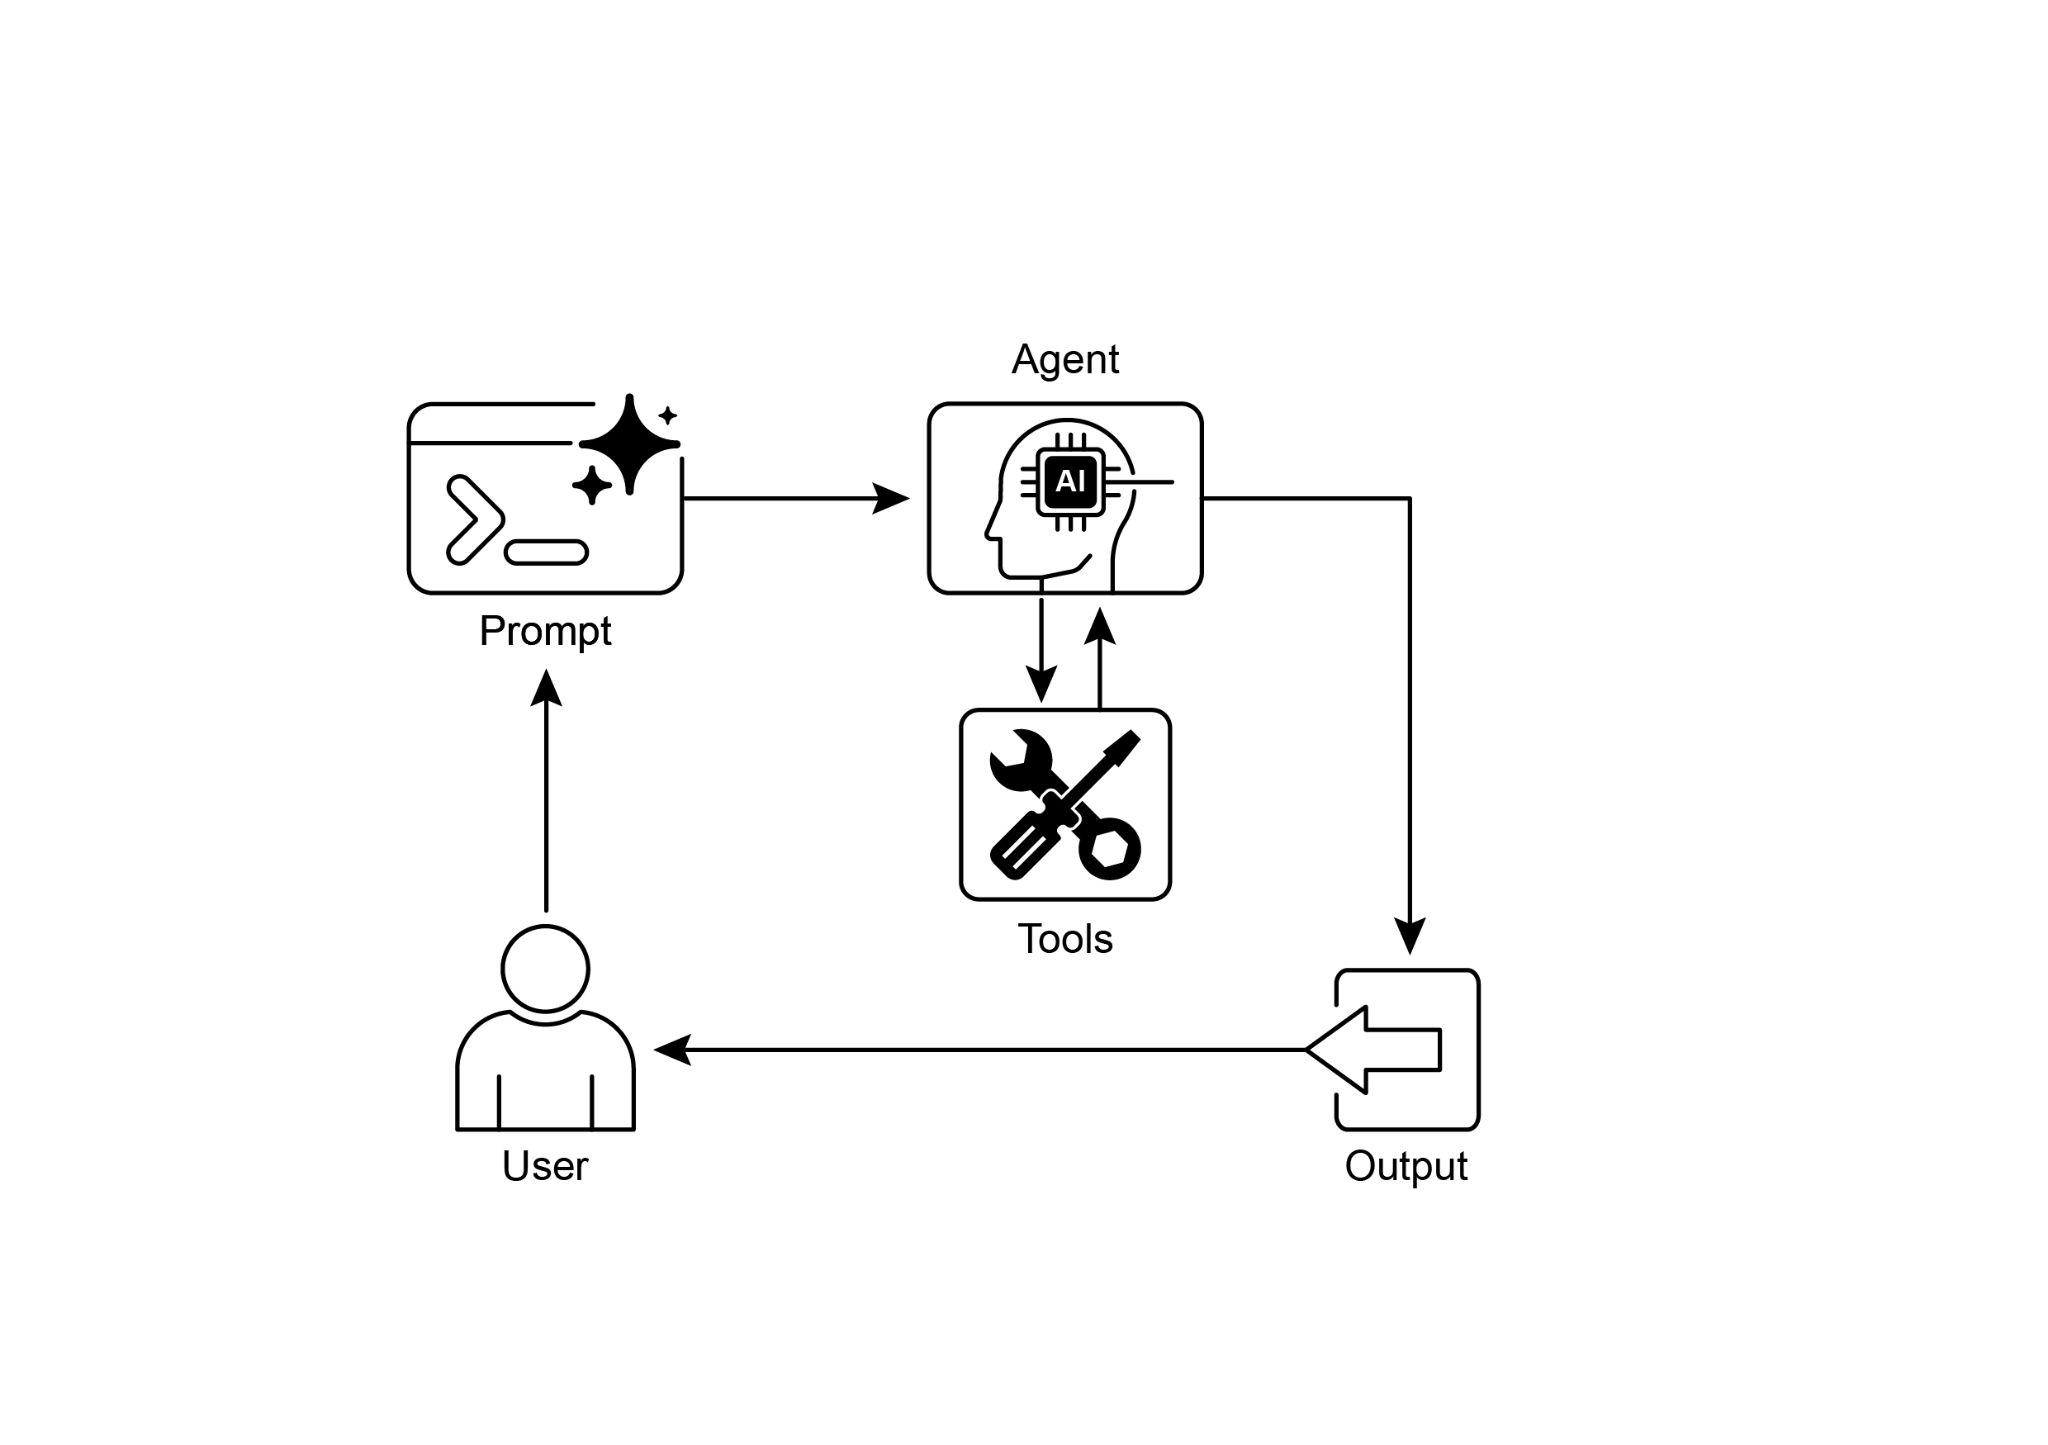
图 2:工具使用设计模式。
要点
- 工具使用(函数调用)让智能体能够与外部系统交互,并获取动态信息。
- 工具需要以清晰的描述和参数定义呈现给 LLM。
- LLM 负责判断何时调用工具,并生成结构化的调用请求。
- 智能体框架负责执行真实的工具调用,并将结果返回给 LLM。
- 如果要构建能够采取真实行动、提供最新信息的智能体,工具使用不可或缺。
- LangChain 可借助
@tool等方式简化工具定义,并通过create_tool_calling_agent与 AgentExecutor 搭建会用工具的智能体。 - Google ADK 提供 Google 搜索、代码执行、Vertex AI Search 等实用的预置工具。
结语
工具使用模式(Tool Use) 是扩展大语言模型能力边界、突破纯文本生成局限的关键架构原则。为模型接通外部软件与数据源后,智能体才得以执行动作、完成计算并从其他系统取数;当模型判断只有调用外部工具才能满足用户请求时,就会生成结构化的工具调用请求。LangChain、Google ADK、CrewAI 等框架为集成外部工具提供了相应的抽象与组件,负责向模型暴露工具规约,并解析后续的工具调用请求,从而简化能够在外部数字环境中交互并采取行动的高级智能体系统的开发。
参考资料
- LangChain 文档(工具):https://python.langchain.com/docs/integrations/tools/
- Google 智能体开发套件(ADK)文档(工具):https://google.github.io/adk-docs/tools/
- OpenAI 函数调用文档:https://platform.openai.com/docs/guides/function-calling
- CrewAI 文档(工具):https://docs.crewai.com/concepts/tools